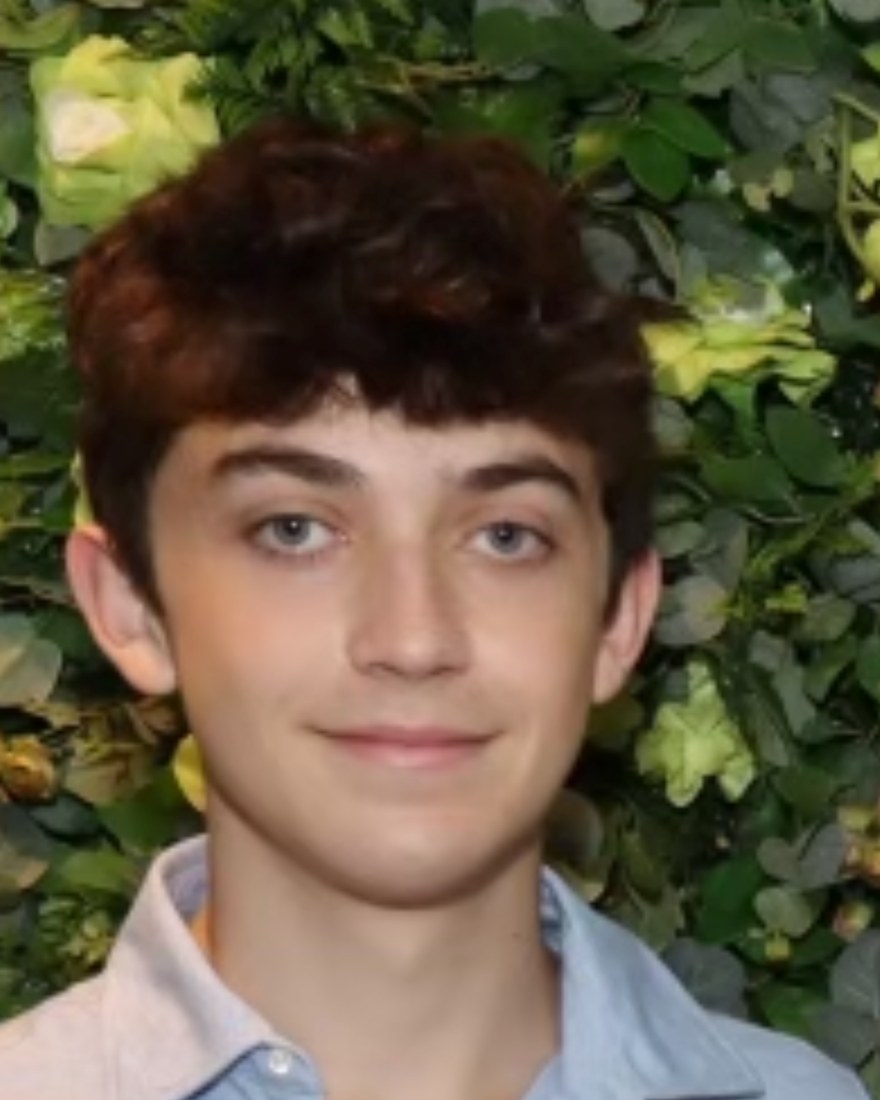
Rising junior at Newark Academy. I build sports analytics tools that answer questions I actually have — in R, on real play-by-play data, with the pipeline documented end to end.

I am a rising junior at Newark Academy, and I am very passionate about sports — I follow a wide variety of teams, athletes, and competitions. One of my biggest interests is sports analytics: using statistics and data to better understand player performance, team strategy, and the factors that actually contribute to winning.
I enjoy looking beyond the final score to analyze trends, metrics, and decision-making in sports. That work has sharpened my critical thinking more than any class has — when a dataset is wrong, nobody tells you; you find out because a chart looks strange and you have to go figure out why. Every project on this site is something I built, and the data pipeline behind each one is documented and reproducible.
My research sits at the intersection of sports, data science, and product development.
Data wrangling with the tidyverse, visualization with ggplot2, reproducible research with R Markdown, and interactive reporting with flexdashboard.
Building interactive web applications that allow users to explore sports data through custom dashboards, filters, and dynamic visualizations.
Quarterback efficiency, player comparison frameworks, play-by-play data analysis using nflfastR, and building scouting-style reports with code.
Player performance modeling, fantasy basketball optimization, shot chart analysis, and building data pipelines from public NBA APIs.
Clear, honest visual storytelling. Using color, layout, and interactivity to make complex sports data accessible for any audience.
Every project is designed to be shown. Production-quality code, clean design, and work that demonstrates real capability.
Interactive applications built with R and Shiny. Click any project to explore it live or see its current progress.
My first Shiny app. The hosted version is offline now, but the full build walkthrough — layout, reactivity, the mistakes — is written up.
Comprehensive player lookup and comparison tool with advanced metrics, scouting profiles, and trend analysis.
642,472 rows of 2025–26 play-by-play. Fantasy leaderboard, percentile fingerprints, a half-court shot heatmap and full standings — all precomputed, no live API.
Notes on what I am learning, building, and thinking about.
The NFL Data Explorer, start to finish: what reactivity actually means, the bug that re-read my data on every keystroke, and why I sketch the UI on paper now.
R / Shiny48,771 plays from the 2025 season. Why passer rating is a bad metric, what EPA per play measures, and the sack that cost me four points of completion percentage.
NFL AnalyticsThe Hoop Vision pipeline: a shot chart shaped like a butterfly, All-Star teams posing as franchises, and a column that reads zero on every miss.
Data PipelineWithout letting it do the thinking. My prompt→review→break→fix loop, and the afternoon a confidently wrong answer cost me because I reviewed the code instead of the output.
ProcessOpen to conversations about analytics, internships, or collaboration.